More resources, same root cause
Why upgrading CPU, RAM or IOPS rarely solves a mission-critical database slowdown — and what to check before signing the purchase order.
Why upgrading CPU, RAM or IOPS rarely solves a mission-critical database slowdown — and what to check before signing the purchase order.
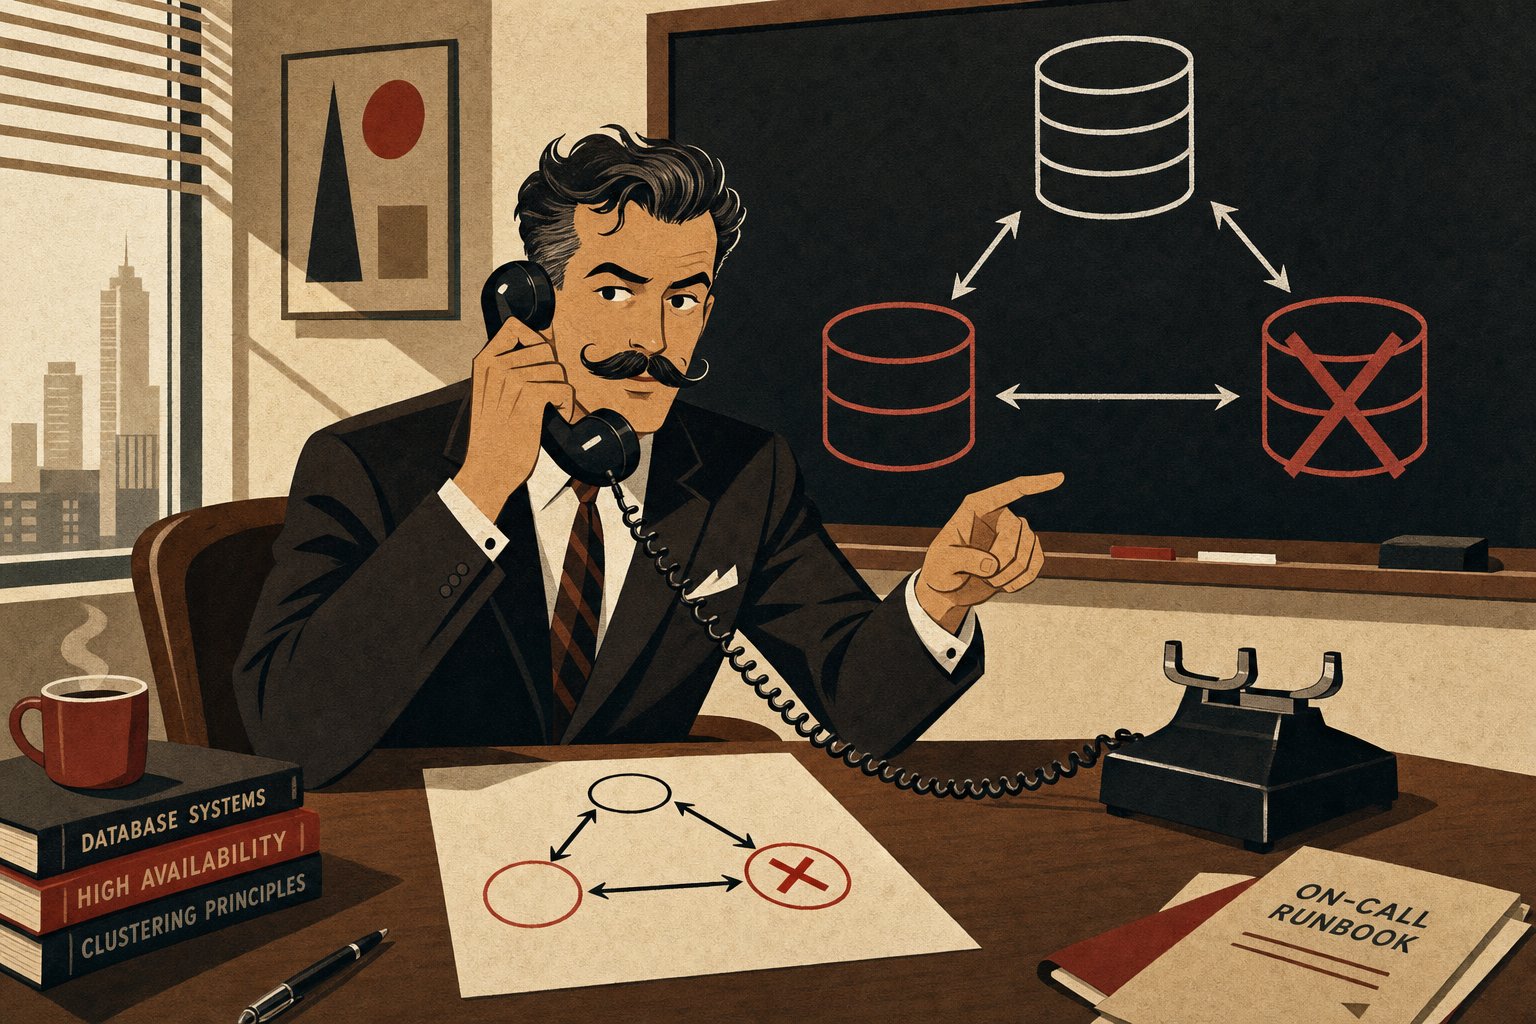
A Galera 3-node cluster loses quorum during a live incident. Diagnosis, emergency bootstrap, and recovery procedure guided over the phone — with the runbook.
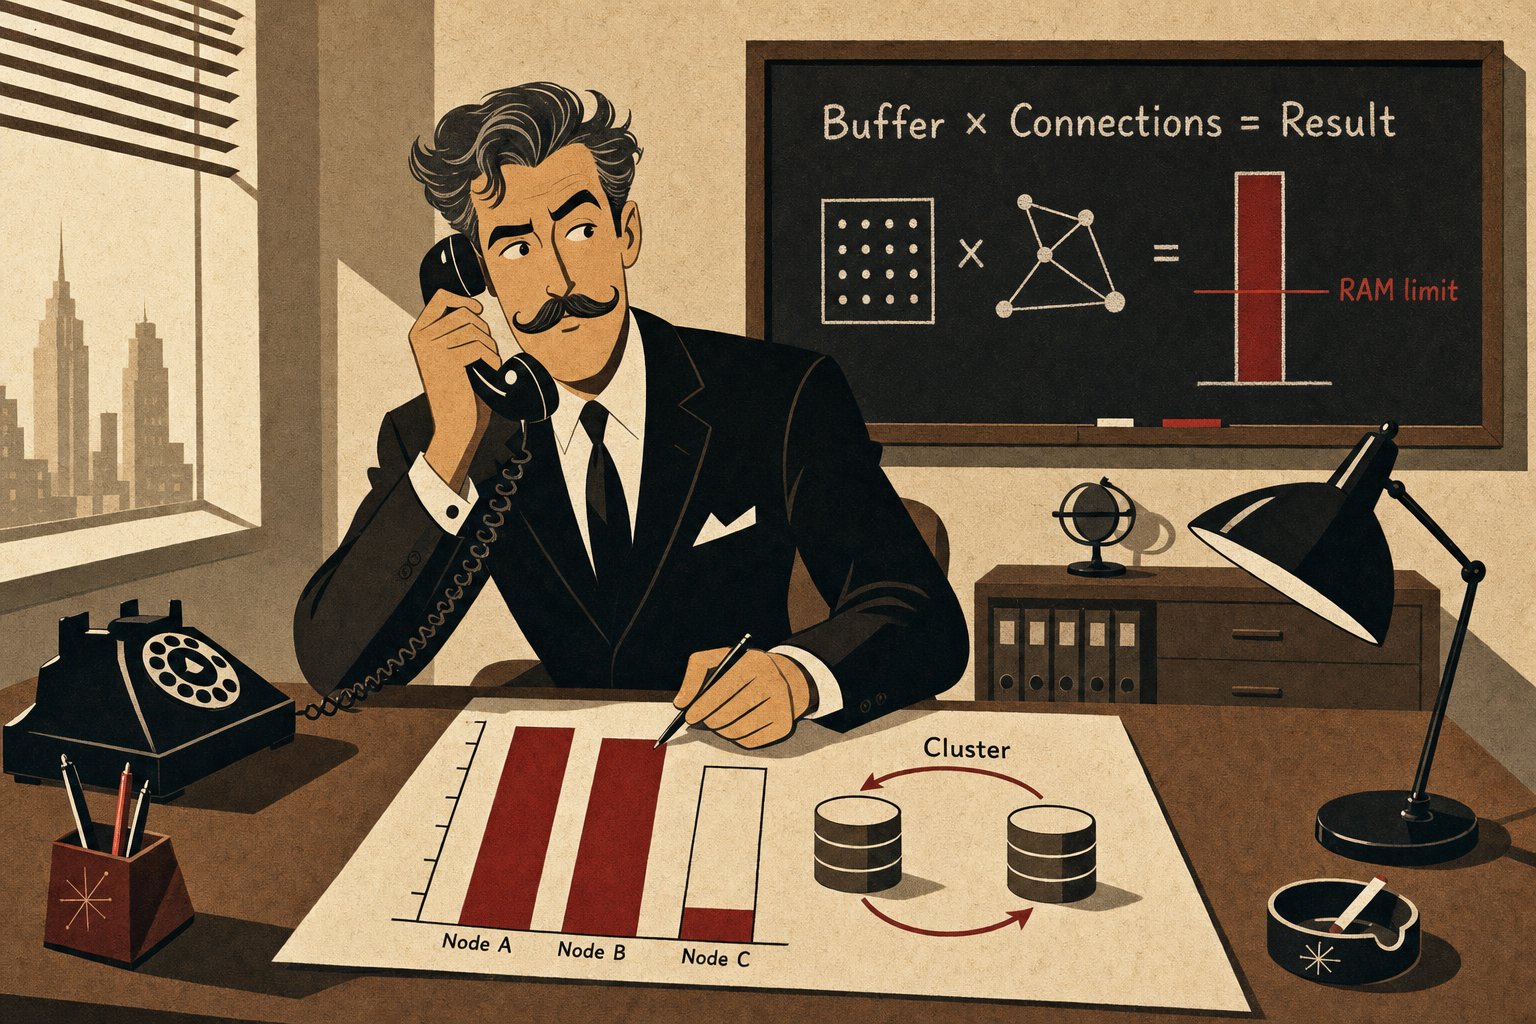
A MySQL InnoDB Cluster grinding to a halt due to join_buffer_size set to 2 GB per thread. Diagnosis, rolling restart, and the math behind per-thread buffers.
Step-by-step diagnosis of ORA-00205 during a night emergency: MOUNT phase, control file, SPFILE, redo log. A practical method for on-call Oracle DBAs.
Start typing to search…
Select a result to see the preview