- Ivan Luminaria/
- Database Strategy/
- MySQL/
- 128 MB on a 32 GB machine: InnoDB buffer pool sizing in production/
128 MB on a 32 GB machine: InnoDB buffer pool sizing in production
128 MB on a 32 GB machine #
The alert came in on a Thursday morning: average query latency climbing, spikes above 100ms on operations that should have been fast. An e-commerce application, MySQL 8.0, server with 32 GB of RAM. The team had already looked at indexes, already reviewed the slowest queries, already added a few EXPLAIN calls. Everything looked reasonable on paper.
Then someone checked innodb_buffer_pool_size.
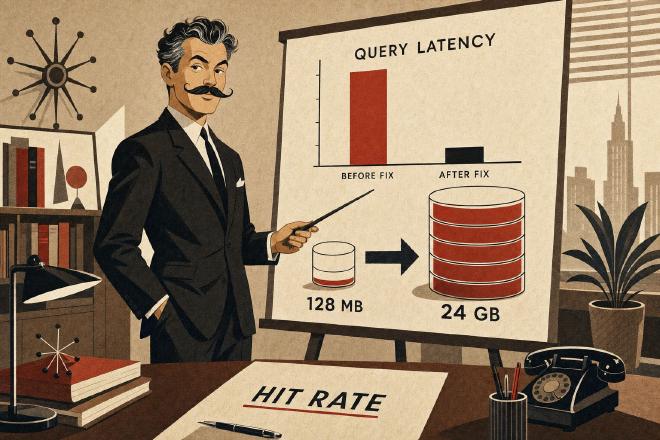
128 MB. The default value. On a machine with 32 GB of available RAM, MySQL was using 128 MB as its InnoDB data cache. 95% of reads were hitting disk. The buffer pool hit ratio was below 50%.
It wasn’t a query problem. It was a basic configuration problem that nobody had touched since the initial provisioning.
What the buffer pool actually does #
The buffer pool is InnoDB’s central memory structure. When MySQL reads a page from disk — whether it’s a table row, a B-tree index node, or undo data — it loads it into memory in the buffer pool. Subsequent reads of the same page are served from RAM, not disk. On writes, InnoDB modifies the page in memory first (a “dirty” page) and then syncs it to disk in the background via the flush mechanism.
The internal structure uses a variant of the LRU (Least Recently Used) algorithm: the most recently accessed pages stay at the top, the least-used ones get evicted to make room for new ones. InnoDB implements a two-zone version — a “young list” for recently accessed pages and an “old list” for eviction candidates — to prevent full scans of large tables from flushing hot pages out of cache [1].
Dirty pages are written to disk by a background flush thread. The innodb_io_capacity parameter controls how many I/O operations per second InnoDB can use for this purpose. If the buffer pool is too small, the eviction rate is high, dirty pages get flushed continuously, and disk becomes the bottleneck even on fast hardware.
With 128 MB of buffer pool and tables collectively occupying several GB, every query touching non-recent data hits disk. On an e-commerce application with access patterns spread across product catalog, orders, and user sessions, the result is exactly what the team was seeing: high latency, saturated I/O, relatively idle CPU.
The 70–80% rule — and when not to apply it #
The standard recommendation for a MySQL-dedicated server is to assign between 70% and 80% of available RAM to the buffer pool [2]. On 32 GB, that means between 22 and 26 GB. In this case, we landed at 24 GB — roughly 75%.
-- Check the current value
SHOW VARIABLES LIKE 'innodb_buffer_pool_size';

-- Resize at runtime (MySQL 5.7.5+, InnoDB dynamic resize)
SET GLOBAL innodb_buffer_pool_size = 25769803776; -- 24 GB in bytes
From MySQL 5.7.5 onward, buffer pool resizing happens online without a restart, though the operation isn’t instantaneous: InnoDB resizes the pool in chunks, and there’s a slight performance impact during the process. It’s worth doing it during a low-traffic window the first time, then the value goes into the configuration file.
# /etc/mysql/mysql.conf.d/mysqld.cnf
[mysqld]
innodb_buffer_pool_size = 24G
The 70–80% rule applies to dedicated servers. If the machine also hosts the application, a web server, or other processes with significant memory footprints, you need to come down from that. A system that swaps to disk because of the buffer pool is worse than a small buffer pool: swap is far slower than any normal database I/O.
Buffer pool instances: mutex contention #
With a large buffer pool, a second parameter comes into play: innodb_buffer_pool_instances.
The buffer pool is protected by internal mutexes. On systems with many concurrent threads, a single large pool becomes a bottleneck due to lock contention. The solution is to split the pool into independent instances, each with its own set of mutexes and its own LRU list [3].
The practical rule of thumb: one instance per GB of buffer pool, up to a maximum of 64. For 24 GB, 8 instances is a reasonable starting point.
[mysqld]
innodb_buffer_pool_size = 24G
innodb_buffer_pool_instances = 8
One important detail: innodb_buffer_pool_instances only takes effect if innodb_buffer_pool_size is at least 1 GB. With the 128 MB default, the parameter is silently ignored. That’s another reason the problem was invisible until someone actually looked at the base configuration.
On high-concurrency workloads — and an e-commerce application with traffic spikes qualifies — the difference between one and eight instances can be measurable even after resolving the main sizing issue.
Reading the signals: hit ratio and dirty pages #
Before touching any parameter, the starting point is understanding what’s actually happening. SHOW ENGINE INNODB STATUS is the command that tells you what’s going on inside InnoDB at any given moment [4].
SHOW ENGINE INNODB STATUS\G
The output is verbose. The relevant section for the buffer pool is BUFFER POOL AND MEMORY:
----------------------
BUFFER POOL AND MEMORY
----------------------
Total large memory allocated 137363456
Dictionary memory allocated 409606
Buffer pool size   8192
Free buffers       1024
Database pages     7168
Old database pages 2624
Modified db pages  512
Pending reads      0
Pending writes: LRU 0, flush list 0, single page 0
Pages made young 1847392, not young 284719
0.00 youngs/s, 0.00 non-youngs/s
Pages read 9284719, created 48291, written 284719
0.00 reads/s, 0.00 creates/s, 0.00 writes/s
Buffer pool hit rate 501 / 1000, young-making rate 0 / 1000 not 0 / 1000
The key line is Buffer pool hit rate. In the X / 1000 format, a value of 501 means a 50.1% hit ratio — one out of every two reads goes to disk. The production target is to stay above 990/1000, ideally 995+.
For more granular monitoring, the performance_schema and information_schema tables expose per-instance metrics:
SELECT
  pool_id,
  pool_size,
  free_buffers,
  database_pages,
  hit_rate,
  pages_made_young,
  pages_not_made_young
FROM information_schema.INNODB_BUFFER_POOL_STATS;
Modified db pages (dirty pages) deserve attention: a high and stable number indicates that the flush thread can’t keep up with writes. If it’s climbing steadily, that’s a signal to revisit innodb_io_capacity relative to the available hardware.
The restart and the cold start problem #
There’s one aspect of the buffer pool that often gets ignored until the first production restart: after a reboot, the pool is empty. All the hot pages that were in memory are gone. The system starts cold, and for a variable period — anywhere from minutes to hours, depending on workload and pool size — performance is degraded while InnoDB progressively reloads data from disk.
MySQL offers a mechanism to mitigate this: buffer pool dump and restore [5].
[mysqld]
# Save the buffer pool on shutdown
innodb_buffer_pool_dump_at_shutdown = ON

# Percentage of pages to save (default 25)
innodb_buffer_pool_dump_pct = 25

# Load the buffer pool on startup
innodb_buffer_pool_load_at_startup = ON
With innodb_buffer_pool_dump_at_shutdown = ON, MySQL saves the identifiers of the pages that were in the pool at shutdown to a file (by default ib_buffer_pool in the datadir). On the next startup, with innodb_buffer_pool_load_at_startup = ON, the pages are reloaded in the background.
The file contains only identifiers (tablespace ID and page number), not the actual data: the restore requires MySQL to re-read the pages from disk, but it does so in an organized and prioritized way, significantly reducing warm-up time.
You can also trigger the dump and restore manually at runtime, without waiting for a shutdown:
-- Manual buffer pool dump
SET GLOBAL innodb_buffer_pool_dump_now = ON;

-- Manual restore (useful after an unplanned restart)
SET GLOBAL innodb_buffer_pool_load_now = ON;

-- Monitor restore progress
SHOW STATUS LIKE 'Innodb_buffer_pool_load_status';
In this case, after configuring the automatic dump and doing a controlled restart to apply the new parameters, warm-up took about 8 minutes instead of the 40–50 that would have been expected with a completely cold 24 GB pool. No magic: it’s that the top 25% of hottest pages covers the vast majority of real-world access patterns.
The numbers, before and after #
The comparison is clear:
| Metric | Before | After |
|---|---|---|
innodb_buffer_pool_size | 128 MB | 24 GB |
innodb_buffer_pool_instances | 1 | 8 |
| Hit ratio | ~50% | ~997/1000 |
| Disk reads | ~95% | <1% |
| Average query latency | 45ms | 3ms |
| Throughput (queries/s) | baseline | ~2× |
The drop from 45ms to 3ms latency isn’t the result of a rewritten query or a new index. It’s the result of stopping disk reads for data that could have lived in RAM. Disk was the bottleneck, and the bottleneck had been there since day one of provisioning.
The doubled throughput is a direct consequence: less waiting on I/O means more queries served in the same time, with the same CPU.
What’s worth keeping in mind #
The buffer pool isn’t the only parameter that matters in MySQL, but it’s probably the one with the highest impact-to-complexity ratio. A server with 32 GB of RAM and 128 MB of buffer pool is like a warehouse with 32 rooms that only uses one to store inventory: the work still gets done, but at enormously higher cost.
The point isn’t that the default is wrong in absolute terms — 128 MB makes sense on a shared machine with limited RAM or in a development environment. The point is that the default never gets revisited at production provisioning time, and nobody notices until the system starts struggling.
Diagnosis always starts with the hit ratio. If it’s below 990/1000, the buffer pool is the first place to look. Then come instances, then warm-up, then everything else.
The team also set up an alert on the hit ratio: below 985/1000 for more than five minutes, a notification fires. Not because anyone expects to be back at square one, but because systems change — data grows, access patterns shift, a new module ships — and it’s better to know before latency climbs back to 45ms.
Official sources #
- MySQL 8.0 Reference Manual — Making the Buffer Pool Scan Resistant
- MySQL 8.0 Reference Manual — Configuring InnoDB Buffer Pool Size
- MySQL 8.0 Reference Manual — Configuring Multiple Buffer Pool Instances
- MySQL 8.0 Reference Manual — SHOW ENGINE INNODB STATUS
- MySQL 8.0 Reference Manual — Saving and Restoring the Buffer Pool State
Glossary #
InnoDB buffer pool — InnoDB’s primary memory area where data and index pages are cached. The larger it is, the fewer reads hit disk. Parameter:
innodb_buffer_pool_size.Hit ratio (buffer pool) — Percentage of reads served from memory relative to the total. Expressed in X/1000 format in
SHOW ENGINE INNODB STATUSoutput. Values below 990/1000 indicate excessive disk dependency.Dirty page — A buffer pool page that has been modified in memory but not yet synced to disk. InnoDB manages these via background flush; a high and growing count signals that the flush thread can’t keep pace with writes.
LRU list (InnoDB) — A two-zone structure (young list + old list) used by InnoDB to decide which pages to keep in cache and which to evict. Protects hot pages from being displaced by occasional full scans.
Buffer pool warm-up — The process of reloading hot pages into the buffer pool after a restart. With
innodb_buffer_pool_dump_at_shutdownandinnodb_buffer_pool_load_at_startup, MySQL saves and restores page identifiers, reducing cold start time from hours to minutes.