- Ivan Luminaria/
- Database Strategy/
- MySQL/
- The 8:40 AM phone call: recovering a Galera Cluster when nodes fall one after another/
The 8:40 AM phone call: recovering a Galera Cluster when nodes fall one after another
The 8:40 AM phone call #
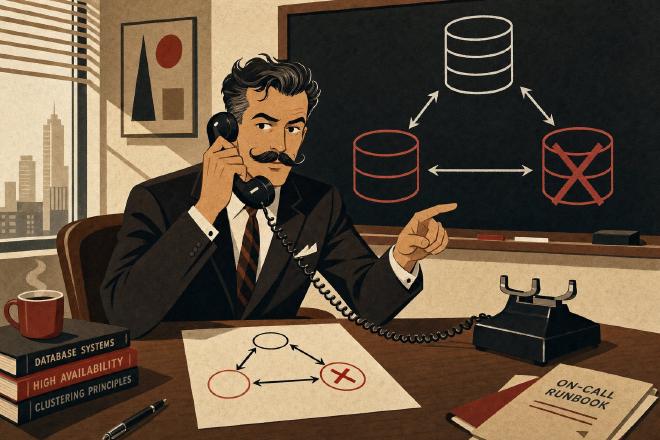
It was early morning. I was finishing my first coffee when the phone rang: a colleague on-site at a client, voice a little tense. He tells me the monitoring system had just fired two alerts in sequence on a three-node Galera cluster. He reads me the first ticket:
Galera Cluster, one node is down. Detected value: 2. Node that generated the alert:
mysql-node-01.
wsrep_cluster_size = 2. One node out. I tell him it’s not an immediate emergency — the cluster is still operational with two nodes out of three, quorum holds. “Open a console on the node that alerted and let’s see what happened,” I suggest. But while he was connecting via SSH, the second ticket arrives:
Galera Cluster, one node is down. Detected value: 2. Node that generated the alert:
mysql-node-02.
Two tickets, almost back to back. The second came from a different node, but still reported 2 as the value — which meant the cluster, from mysql-node-02’s perspective, still had two members. “OK, now the situation changes,” I tell him. “Which of the two was left standing? Was the node that fired the first alert already down when the second one came in, or not?”
This article is the natural sequel to the one on configuring a 3-node Galera Cluster [article #33]. That one explains how to build it. This one tells you what happens the day nodes start falling one after another — and how you get back to operational, possibly while guiding a colleague over the phone with the client standing right behind him.
How the cluster counts its members (and why that number is everything) #
Before passing him commands to run, I asked for thirty seconds to remind him of the mechanism generating those alerts — because in a panic it’s easy to look at numbers without actually reading them.
Galera maintains internally the concept of the Primary Component (PC): the subset of nodes that holds quorum and can continue processing writes. When a node leaves, the remaining ones agree on who belongs to the PC through the membership protocol. The variable that exposes this state is wsrep_cluster_size [1]:
SHOW GLOBAL STATUS LIKE 'wsrep_cluster_size';
SHOW GLOBAL STATUS LIKE 'wsrep_cluster_status';
SHOW GLOBAL STATUS LIKE 'wsrep_local_state_comment';
In a healthy 3-node cluster, wsrep_cluster_size reads 3 on all nodes and wsrep_cluster_status reports Primary. When a node leaves, the two remaining ones see wsrep_cluster_size = 2 — but they keep operating because they still have quorum (2 out of 3 > 50%).
The situation becomes critical when two out of three nodes go down. The surviving node has no quorum: it can’t tell whether it’s the one that’s isolated or whether the other two are having problems. To prevent split-brain — two partitions both accepting diverging writes — Galera applies a simple rule: no quorum, no writes. The surviving node transitions to non-Primary state and stops accepting DML.
The client’s monitoring was configured to alert on wsrep_cluster_size < 3. Correct. But the two near-simultaneous alerts suggested a more complex scenario than a simple node restart — and I wanted my colleague to understand that before typing any invasive command.
Diagnosis: figuring out what had actually happened #
“The first thing we do is build a timeline,” I tell him. “Who went down first? What state are the nodes in right now? Go to the third node, the one that didn’t fire any alert.”
On the third node (mysql-node-03, the silent one), I have him run:
SHOW GLOBAL STATUS LIKE 'wsrep%';
He reads me the relevant output:
wsrep_cluster_size          | 1
wsrep_cluster_status        | non-Primary
wsrep_local_state_comment   | Initialized
wsrep_connected             | ON
wsrep_ready                 | OFF
“OK, ugly situation,” I comment. wsrep_cluster_size = 1 and wsrep_cluster_status = non-Primary. The node was still up, connected to the network, but not accepting writes. It had lost quorum.
I ask him to try connecting to the other two. On mysql-node-01 and mysql-node-02 MySQL isn’t responding — both down. I have him open the error log on mysql-node-01 and he reads me:
[ERROR] WSREP: gcs/src/gcs_group.cpp:gcs_group_handle_join_msg():736:
  Member 1 (mysql-node-02) requested state transfer from '*any*'.
[Warning] WSREP: Member 1 (mysql-node-02) is waiting for SST from donor.
[ERROR] WSREP: Process completed with error: wsrep_sst_xtrabackup-v2 ...
[ERROR] WSREP: SST failed: 32 (Broken pipe)
“Here’s the sequence,” I explain. mysql-node-01 had gone down first (probably a network issue or OOM), mysql-node-02 had tried to rejoin the cluster via SST (State Snapshot Transfer), the SST had failed, and in the meantime mysql-node-02 had gone down too. The remaining node, mysql-node-03, had found itself alone and lost quorum.
The most common causes worth ruling out #
“Before we proceed to recovery, let’s understand why a node leaves,” I tell him. Not needed for the immediate fix, but to avoid finding ourselves in the same situation two hours from now. The most frequent causes in production:
- Network issues: high latency or packet loss between nodes. Galera uses
evs.suspect_timeoutandevs.inactive_timeoutto decide when to evict a node. A slow-responding node gets evicted even if MySQL itself is healthy. - OOM killer: the Linux kernel terminates
mysqlddue to memory pressure. Visible indmesgor/var/log/messages. - Slow applier: the node can’t keep up with the writeset flow. A high
wsrep_local_recv_queue_avgis a signal. - gcache overflow: if the node has been offline long enough that the required writesets are no longer in the other nodes’ gcache, it can’t do IST and must do SST — which is far heavier.
I have him check dmesg on mysql-node-01. Ten seconds later: Out of memory: Kill process [mysqld] about 20 minutes before the first alert. OOM killer, prime suspect. I make a mental note for later — first we recover the cluster.
SST and IST: rejoining the cluster isn’t the same thing twice #
“Now let me explain why the SST failed, so you understand what we need to avoid when we bring the nodes back,” I tell him.
When a node rejoins after an absence, Galera needs to sync it with the cluster’s current state. There are two modes [2]:
IST (Incremental State Transfer): the node receives only the writesets it missed, from the other nodes’ gcache. It’s fast, doesn’t disrupt the donor, doesn’t require a full backup. It only works if the gap is small and the required writesets are still in the gcache.
SST (State Snapshot Transfer): a full state transfer — essentially a physical backup (using xtrabackup, mysqldump, or rsync) from the donor to the joiner. It’s slow, can put the donor under pressure, and during SST the donor may become unresponsive to reads (depending on the method). It’s necessary when the gap is too large for IST.
The practical distinction: if a node has been offline for a few minutes and the gcache is sized correctly (wsrep_provider_options = "gcache.size=2G" as a starting point), IST is almost guaranteed. If the node has been offline for hours or days, SST is unavoidable.
“In your case,” I tell him, “the failed SST is the critical point.” mysql-node-02 had tried to rejoin, the donor had started the transfer, but something had interrupted the process (the Broken pipe in the log suggested a connection problem during the transfer). And in the meantime mysql-node-02 had been left in an inconsistent state — neither in nor out.
The recovery procedure: order and patience #
“OK, now let’s put this back together. With two nodes down and one in non-Primary, order matters more than anything else. Don’t touch anything before I tell you to.”
Step 1: identify the most up-to-date node #
Before bringing any node back, you need to know which one has the most advanced transaction sequence. That’s the node that will become the donor for the others.
“Go to each node, even the ones with MySQL down, and read me Galera’s state file”:
cat /var/lib/mysql/grastate.dat
Typical output:
# GALERA saved state
version: 2.1
uuid:    6b3f8c2a-1234-11ee-abcd-0242ac110003
seqno:   847392
safe_to_bootstrap: 0
The node with the highest seqno is the most up-to-date. If safe_to_bootstrap: 1, Galera itself has already identified that node as safe for bootstrap. If all nodes show safe_to_bootstrap: 0 (common after a simultaneous crash), you need to manually pick the node with the highest seqno and edit the file.
Step 2: bootstrap the most up-to-date node #
“Now comes the delicate part, so follow me step by step and don’t rush.” The emergency bootstrap is the most critical moment: you’re starting the first node as a new Primary Component, without waiting for the others.
# On the node with the highest seqno, edit grastate.dat
# Set safe_to_bootstrap: 1

# Then start with --wsrep-new-cluster
galera_new_cluster
# or, depending on the distribution:
mysqld_safe --wsrep-new-cluster &
This creates a new cluster with a single member. The node becomes Primary and starts accepting writes. Important: if you bootstrap on the wrong node (the one with the lower seqno), you lose the transactions that had already been committed on the more advanced node. “Take two extra minutes and verify the seqno on all three nodes before choosing. Two minutes now beats a complicated rollback later.”
He reads me the values: mysql-node-03 (the only one still standing) had seqno: 847392, while mysql-node-01 showed seqno: 847389. “Good, bootstrap goes on mysql-node-03.”
Step 3: bring nodes back one at a time #
“Wait until the first node is Primary, then we’ll start on the second. One at a time — I mean it.” Start them normally (without --wsrep-new-cluster) and Galera handles the sync:
systemctl start mysql
The rejoining node connects to the cluster, negotiates IST or SST, and syncs. During this phase, I have him keep a monitoring loop open on:
SHOW GLOBAL STATUS LIKE 'wsrep_local_state_comment';
-- Expected progression: Joining -> Waiting for SST -> Joined -> Synced
“Wait for Synced before touching the third node. If you start them all at once you increase the load on the donor and risk another failed SST — and then we start over from scratch.”
Step by step, with my colleague on the phone #
At this point the call had become operational. I was dictating commands, he was running them and reading back the output. Here’s how it went:
- Verified
grastate.daton all three nodes.mysql-node-03had the highest seqno and was already up (innon-Primarystate). - Restarted
mysql-node-03withgalera_new_clusterafter settingsafe_to_bootstrap: 1in itsgrastate.dat. The node immediately moved toPrimarywithwsrep_cluster_size = 1. “Good, let’s breathe for a second.” - Started
mysql-node-01. It negotiated IST (the gap was a few thousand writesets, the gcache was sufficient). Synced in about 3 minutes. My colleague reads meSyncedand I can hear him relax a little. - Started
mysql-node-02. IST again, synced in 4 minutes. - Verified on all three nodes:
wsrep_cluster_size = 3,wsrep_cluster_status = Primary,wsrep_local_state_comment = Synced.
The cluster was back up. The actual write downtime had been about 35 minutes — the time between the second node going down and the bootstrap completing. My colleague closes the call with a “thanks, now I need to go explain to the client what happened.” Most of the credit, I tell him before hanging up, goes to the fact that he kept a cool head and didn’t touch anything before understanding the situation.
What still needs doing after the recovery #
The recovery is the visible part. What matters most is what you do afterward, once the pressure has dropped. In the afternoon I had a second call with my colleague to put in writing what was worth fixing.
On monitoring: the alert on wsrep_cluster_size < 3 was correct, but there was no alert on wsrep_cluster_status != Primary. These are two different conditions: a cluster can have cluster_size = 2 and still be Primary (one node left but quorum holds), or have cluster_size = 1 and be non-Primary (no writes possible). The second scenario requires immediate action; the first has more margin.
On gcache: size the gcache so that IST is possible for short absences. A 512MB gcache on a high write-throughput cluster gets exhausted in minutes. Bumping it to 2–4GB dramatically reduces the need for SST on quick restarts.
On OOM: the original problem was the OOM killer on mysql-node-01. The fix wasn’t in the Galera cluster — it was in MySQL’s memory configuration (innodb_buffer_pool_size set too aggressively for the available RAM) and the absence of swap. Two things that have nothing to do with replication, but in an HA cluster become critical because a process crash propagates as a membership event.
On bootstrap: document the emergency bootstrap procedure in the operational runbook, with the exact commands and correct order. It’s a procedure you run rarely, under pressure, with the client asking for updates every five minutes. That’s not the moment to try to remember it from scratch — or to have to call a colleague because you can’t.
The runbook we wish we’d had that morning #
This is the condensed version of the procedure, to keep within reach — the one my colleague saved to a file in the client’s repo before closing out the day:
# 1. Check state on all nodes
mysql -e "SHOW GLOBAL STATUS LIKE 'wsrep%';" 2>/dev/null || echo "MySQL down"

# 2. Read seqno from grastate.dat (even if MySQL is down)
cat /var/lib/mysql/grastate.dat

# 3. On the node with the highest seqno: enable bootstrap
sed -i 's/safe_to_bootstrap: 0/safe_to_bootstrap: 1/' /var/lib/mysql/grastate.dat

# 4. Bootstrap the first node
galera_new_cluster

# 5. Verify it's Primary
mysql -e "SHOW GLOBAL STATUS LIKE 'wsrep_cluster_status';"

# 6. Start the other nodes one at a time
systemctl start mysql
# Wait for Synced before the next one

# 7. Final check on all nodes
mysql -e "SHOW GLOBAL STATUS LIKE 'wsrep_cluster_size'; SHOW GLOBAL STATUS LIKE 'wsrep_cluster_status';"
Simple on paper. Less simple when you’re at a client site, the second ticket is on your screen, and you’re waiting for someone on the other end of the phone to tell you where to start.
Official sources #
- Codership — Galera Cluster Documentation: wsrep Status Variables <TODO: scout specific URL for wsrep_cluster_size>
- Percona Documentation — State Snapshot Transfer (SST) and Incremental State Transfer (IST)
- Codership — Galera Cluster Recovery <TODO: scout specific URL for emergency bootstrap>
- Percona Blog — gcache sizing <TODO: scout updated URL>
Glossary #
Primary Component (PC) (Galera) — The subset of nodes that holds quorum and can continue processing writes. A node outside the PC transitions to
non-Primarystate and stops accepting DML to prevent split-brain.wsrep_cluster_size (Galera) — Status variable reporting the number of nodes currently in the Galera cluster. Expected value in a 3-node cluster:
3. Dropping below the quorum threshold (≤ 1 out of 3) blocks all writes.IST (Incremental State Transfer) (Galera) — Incremental synchronization for a node rejoining the cluster: it receives only the missing writesets from the other nodes’ gcache. Fast and non-disruptive to the donor; only possible if the gap is covered by the gcache.
SST (State Snapshot Transfer) (Galera) — Full state transfer from a donor node to a joiner: equivalent to a complete physical backup. Required when the gap is too large for IST. Can slow down the donor during the transfer.
gcache (Galera) — A circular on-disk buffer that every Galera node maintains to store recent writesets. Sizing the gcache correctly (
gcache.size) is the primary lever for favoring IST over SST on short restarts.